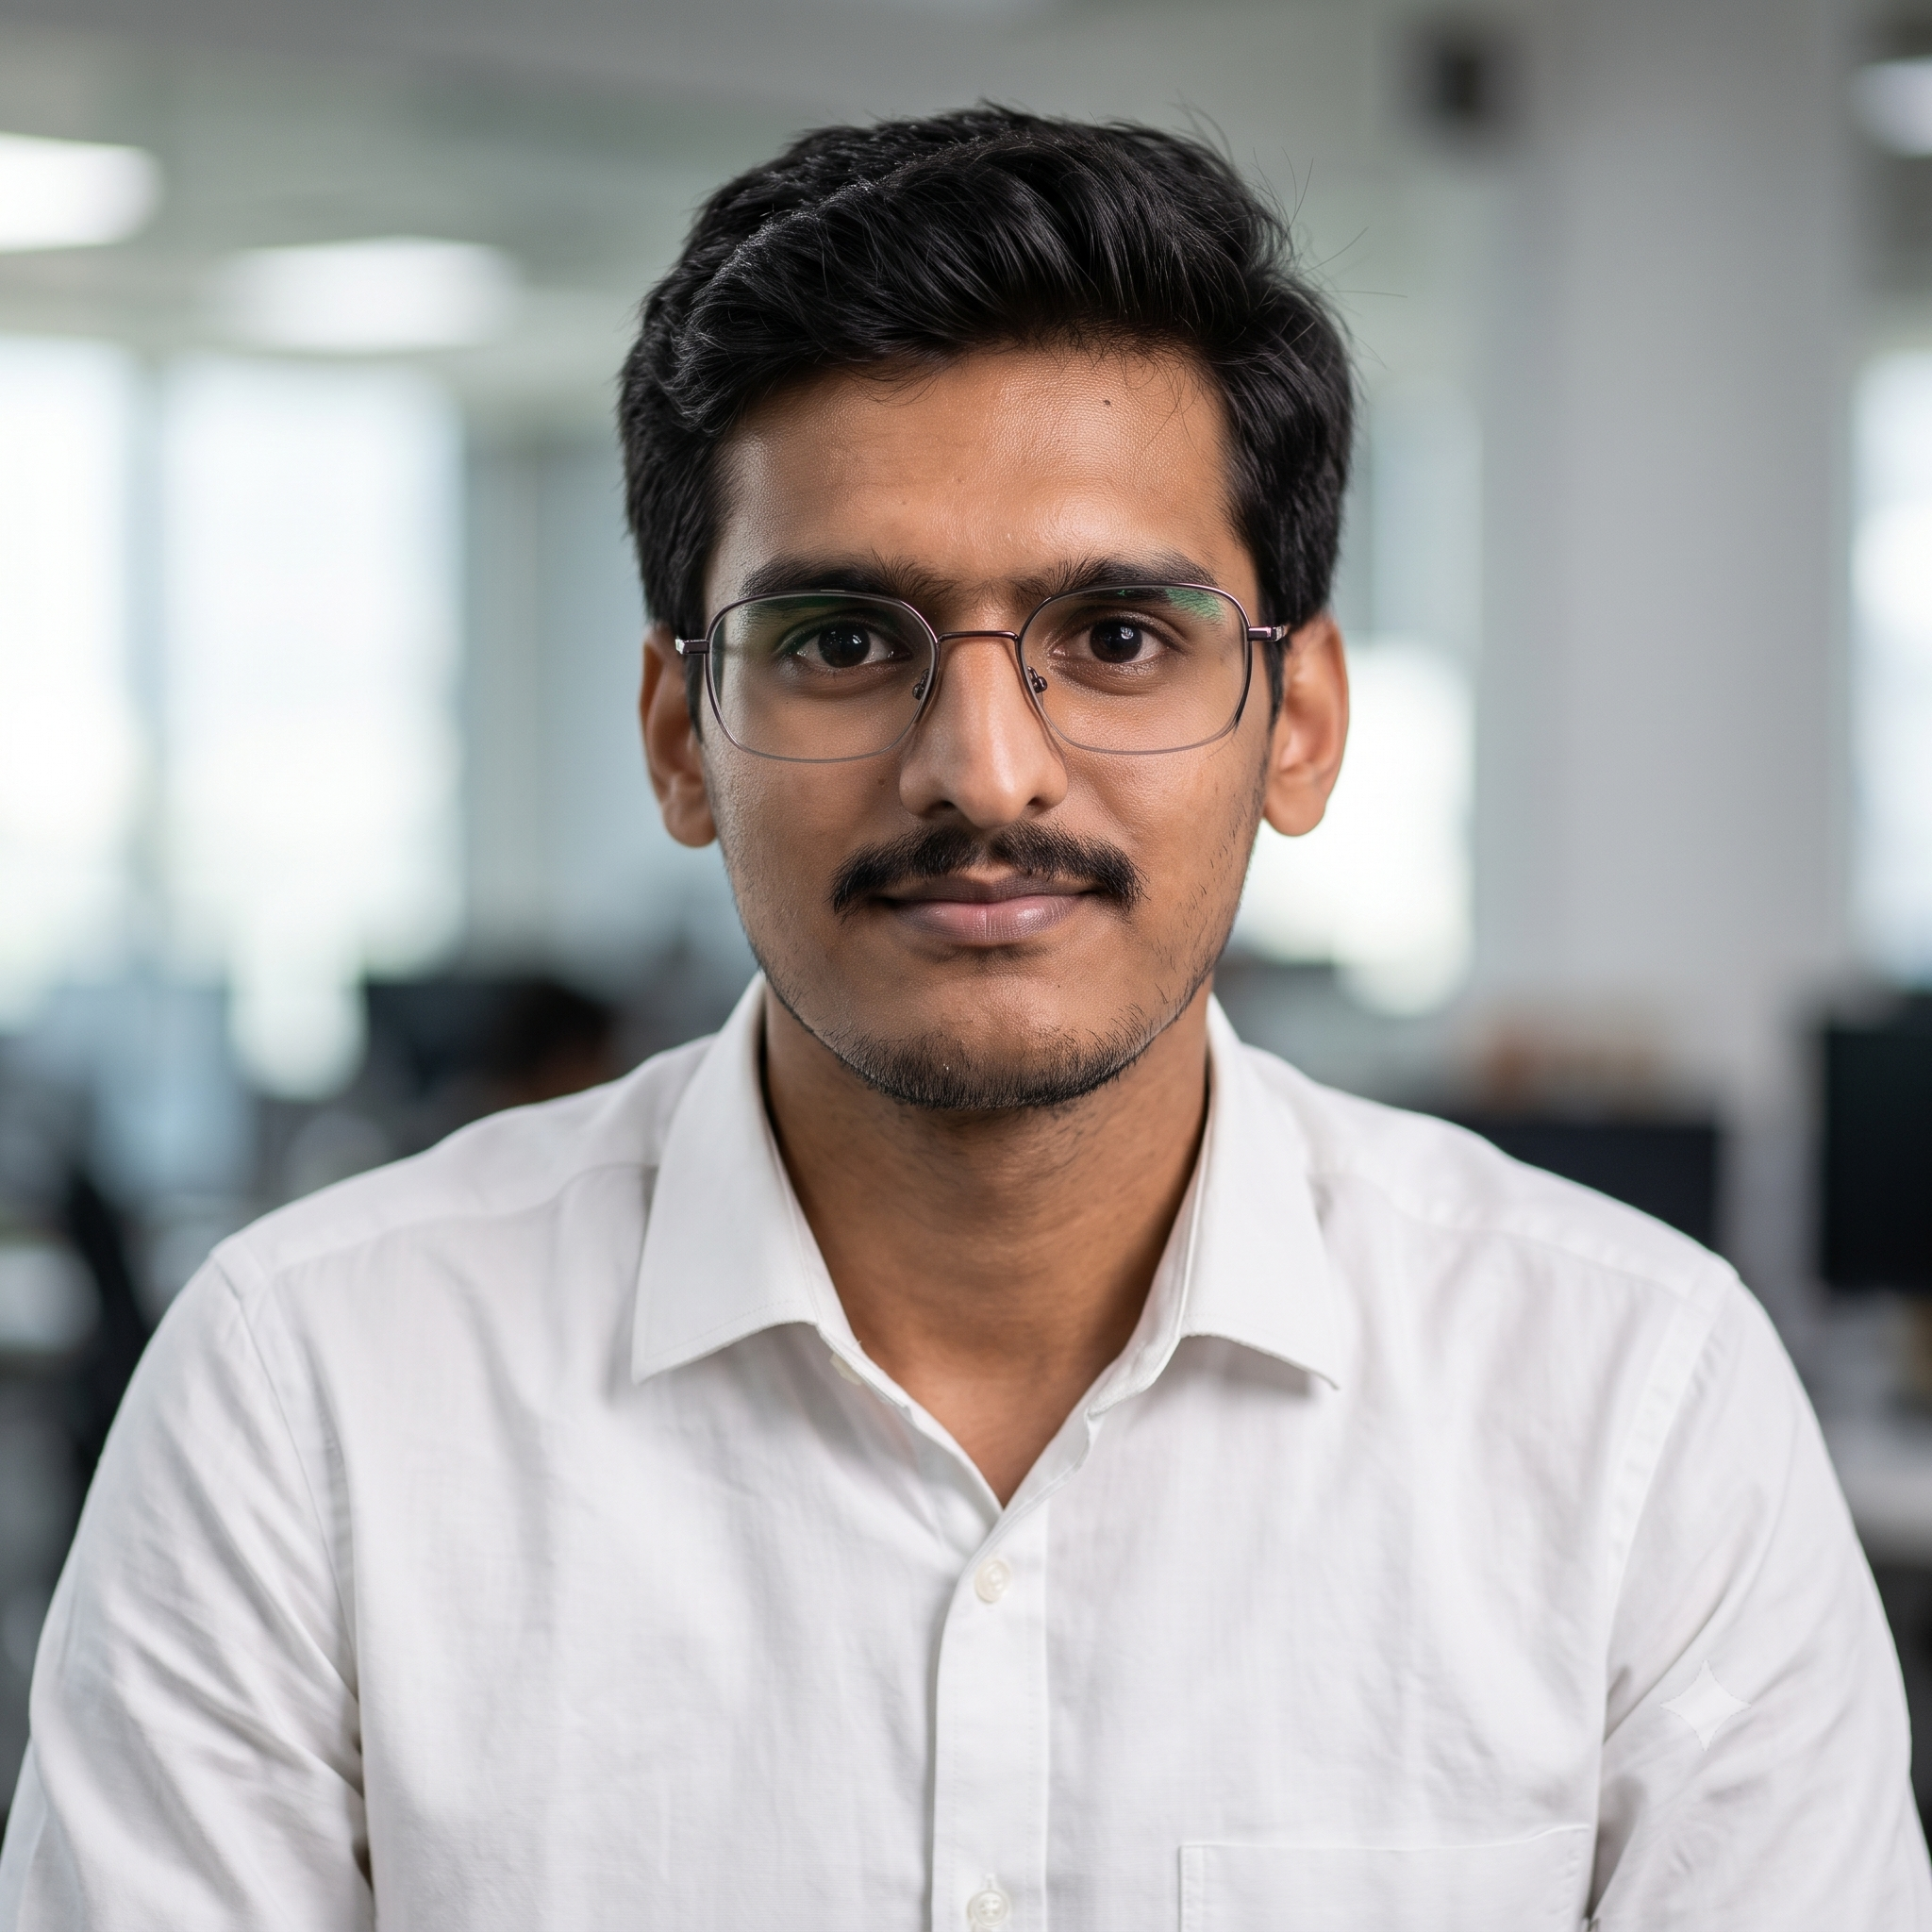
I'm an AI/ML engineer and the creator of OlaiEdge (formerly FastAgent), an open-source local LLM runtime that cut prompt latency from ~3,500 ms to ~73 ms on 8 GB CPU-only hardware with zero OOM crashes; of HERM4AI, a model-free cognitive memory architecture for LLM agents; and of TAEL-Agent, a privacy-preserving autonomous software-engineering agent built on a QLoRA fine-tuned 2B model that runs fully on-device. I also work in computer vision and generative AI, including a real-time wildlife-conflict detection system published in IEEE Xplore. I care more about whether a system holds up under real conditions than whether the demo looks good.
I graduated with a B.Tech in CSE (AI & ML) from Vignan Institute of Technology and Science, Hyderabad, and I'm looking for my first full-time role in AI/ML and software engineering. Right now I'm building TAEL-Agent, a local autonomous SWE agent: IBM Granite 3.1 2B fine-tuned with QLoRA, deployed as a 4-bit GGUF, wrapped in a sandboxed tool runtime with persistent memory and a VS Code extension, all on CPU-only, 8 GB machines. I also created and maintain OlaiEdge (formerly FastAgent), a drop-in local LLM runtime for desktop apps, and published HERM4AI, an open-source cognitive memory architecture for LLM agents that avoids the temporal inversion and prompt-poisoning failures of flat vector RAG. Both have papers on Zenodo.
Before that, WildGuardAI predicted human–wildlife conflict in real time from camera-trap-style footage and was published in IEEE Xplore. I've also shipped full-stack products such as Terrascope AI (a zero-paid-API city intelligence platform) and TalentRank AI. Most of what I build works within real constraints: JivanMitra, my personal AI agent, and my research-agent projects run local-first and offline, because I'm more interested in systems that hold up without a safety net than ones that only work with an API key and a stable connection.
Built a privacy-preserving local autonomous SWE agent for CPU-only, 8 GB RAM systems, fine-tuning IBM Granite 3.1 2B Instruct with QLoRA on a 29,900-sample, three-phase curriculum and deploying a 4-bit GGUF model locally. Engineered an autonomous runtime with 9-category task routing, 10 sandboxed workspace tools, four-pillar persistent memory, and context-budget management. Developed a VS Code extension with code generation, refactoring, diff previews, workspace-aware assistance, and autonomous tool execution; achieved 8/8 benchmark-domain passes in the reported evaluation suite.
GitHub → Hugging Face →Built a headless, drop-in local LLM runtime (SDK + background daemon) on llama.cpp using Longest-Common-Prefix slot caching, 8-bit KV-cache quantization, GBNF grammar-constrained JSON, and a RAM-budget enforcer for desktop apps (Electron/Tauri/Flutter SDKs). Reduced steady-state prompt-evaluation latency from ~3,500 ms to ~73 ms on a CPU-only, 8 GB machine with zero OOM failures in long tool loops; added a process watchdog, multi-tab slot cache, and offline signed licensing; 26 tests.
Designed an open-source, model-free cognitive memory architecture for LLM agents: valid-time store, 7-slot working memory, associative knowledge graph, sleep-phase consolidation, ACT-R arbitration, and Q-MIA provenance; the core engine has zero neural dependencies. Showed that flat vector RAG suffers temporal inversion (41.7% obsolete retrievals), dual collapse (9.0% top-1 at 10k passages), and prompt poisoning (33–40% hallucination); HERM4AI reached 100% on 7 benchmark suites at <2 ms CPU latency, with 36 passing tests.
GitHub → Paper (Zenodo) →Worked on machine learning models and related hands-on AI/ML tasks as part of a remote internship.
Documented parallel processing with n_jobs in GASearchCV. Pull request #178 merged, resolving Issue #152.
Contributed to hands-on AI/ML projects and tasks, building practical experience across the model development workflow.
Built interactive web platform features and visual content. Researched AI-driven ideas for recruitment tools and chatbots, and wrote reports and content for the platform.
Built a smart electricity demand & price forecasting system using Facebook Prophet time-series models, reaching ~95% accuracy on real market datasets. Developed the Flask backend and a Tailwind-styled UI for dynamic date-range inputs with real-time forecast visualization.
Developed an Air Quality Prediction System for Indian cities using Random Forest Regression on PM2.5, PM10, and NOx pollutant data, reaching ~96% AQI category accuracy. Built interactive CLI visualizations and data pipelines across multiple city datasets.
Built a movie recommendation engine suggesting personalized picks based on user preferences and historical data — the earliest version of what's now the Movie Recommendation System project in the archive below.
A headless, drop-in local LLM runtime (SDK + background daemon) for desktop apps. Naive local agent loops re-evaluate the system prompt every turn and let context grow until memory runs out. OlaiEdge wraps llama.cpp with Longest-Common-Prefix slot caching, 8-bit KV-cache quantization, GBNF grammar-constrained JSON, and a RAM-budget enforcer, plus a process watchdog, multi-tab slot cache, and offline signed licensing. Ships with Electron, Tauri, and Flutter SDKs and 26 tests.
Human-like Evolving & Reasoning Memory for AI: a model-free cognitive memory architecture for LLM agents with a valid-time store, 7-slot working memory, associative knowledge graph, sleep-phase consolidation, ACT-R arbitration, and Q-MIA provenance. Shows flat vector RAG fails on temporal inversion (41.7% obsolete retrievals), dual collapse (9.0% top-1 at 10k passages), and prompt poisoning (33–40% hallucination); HERM4AI hits 100% on 7 benchmark suites at <2 ms CPU latency, with zero neural dependencies in the core engine and 36 passing tests.
A privacy-preserving autonomous SWE agent for CPU-only, 8 GB machines. IBM Granite 3.1 2B Instruct fine-tuned with QLoRA on a 29,900-sample, three-phase curriculum and deployed as a 4-bit GGUF. The runtime adds 9-category task routing, 10 sandboxed workspace tools, four-pillar persistent memory, and context-budget management, surfaced through a VS Code extension with diff previews and autonomous tool execution. Passed 8/8 benchmark domains in the reported evaluation suite.
Deep learning system using YOLOv12n, BoT-SORT, and a Kalman Filter to detect animals crossing forest boundaries from live camera feeds. Flask backend with SQLite and GPS-based alerting notifies forest officers and villagers before dangerous encounters happen. Published in IEEE Xplore as "Wild Guard AI: Real-Time Wildlife Conflict Prediction" (2026), and presented at ICICI 2026.
Offline-first, voice-enabled AI companion for elderly users in India. Uses LangChain RAG, agentic AI, LLMs, and NLP to hold context-aware, multilingual conversations in local languages, without depending on a stable internet connection — built for accessibility, not tech fluency.
Local-first, CPU-only AI coding agent (CLI: hwren), currently in active development.
Zero-paid-API platform scoring any city or coordinate across 16 socio-environmental dimensions and 5 personas (family, digital nomad, tourist, retiree, career). Deterministic rule-based scoring over Open-Meteo, OpenStreetMap Overpass, and Wikipedia REST data with a WAL-mode SQLite cache; deployed on Cloudflare Pages.
Live →A local-first, privacy-focused AI assistant built with Ollama and LanceDB, keeping all data and inference on the user's machine.
Explore →A research agent that reads and reasons over documents entirely offline. Rebuilt on Ollama and Mistral after the original API-dependent version proved too fragile for reliable local use.
Explore →AI-assisted recruiting platform: JWT auth, job and candidate management, resume upload, AI scoring and ranking of applicants, hiring analytics dashboard, and recruiter activity feed. React 18 + Vite frontend, Express.js + SQLite backend, deployed on Vercel and Render.
Live → Code →Offline research assistant using RAG, local embeddings, ChromaDB, and Ollama Phi-3 to analyze PDFs with multi-step reasoning.
Explore →An earlier, voice-first iteration of JivanMitra designed to support elderly users in India.
Explore →Hands-free navigation through voice commands in an immersive 3D browser environment, built for accessibility.
Explore →Analyzes and generates EEG signal patterns using deep learning techniques.
Explore →Converts photos or text prompts into downloadable 3D models using open-source AI/ML libraries.
Explore →Search, filter, and browse Pokémon by type and detail using the PokéAPI.
Explore →Predicts future electricity demand and price from historical data through a modern interface.
Explore →Streamlit dashboard forecasting cybercrime trends across Indian states using ARIMA and Polynomial Regression, reaching ~93% accuracy, to support awareness and policy planning.
Explore →Personalized recommendations based on real-time weather conditions to help users make informed decisions.
Explore →A chatbot designed to help parents and elderly users navigate the digital world with confidence.
Explore →Evaluates and compares classification algorithms on the Indicators of Heart Disease dataset.
Explore →A reference implementation of core data analysis and machine learning algorithms in Python.
Explore →Suggests movies based on user preferences using the Nearest Neighbors algorithm.
Explore →Showcases fashion trends and lets users create personal style boards.
Explore →A scalable graph database system for secure healthcare data management with AI-powered insights.
Explore →Personalized fashion recommendations based on event details.
Explore →Browse stylish interior design ideas to inspire and enhance living spaces.
Explore →A flashcard app for efficient learning, with customizable cards and export options.
Explore →Flutter concepts including animations, API integration, and responsive design.
Explore →A model-free cognitive memory architecture for LLM agents (valid-time store, working memory, associative knowledge graph, sleep-phase consolidation, ACT-R arbitration, Q-MIA provenance). Shows flat vector RAG suffers temporal inversion, dual collapse, and prompt poisoning; HERM4AI reaches 100% on 7 benchmark suites at <2 ms CPU latency.
Presents OlaiEdge (formerly FastAgent), a headless inference orchestrator combining LCP slot caching, 8-bit KV-cache quantization, grammar-constrained decoding, and an Adaptive Compute Controller. On a CPU-only 8 GB baseline, steady-state prompt-evaluation latency fell from ~3,500 ms to ~73 ms with no OOM failures during long-running tool loops.
Real-time computer vision system using YOLOv12n, BoT-SORT, and a Kalman Filter to predict human–wildlife conflict from camera feeds, with GPS-based alerts for forest officers and villagers.